Framework, untouched
TradingAgents 0.5.1 and AI Hedge Fund 2.4.0 run as released. Glassbench observes each one through its own adapter with its own tests, so an engine update breaks in one known place and nowhere else.
backend/deskapp/adapter.py
An open-source UI for TradingAgents, AI Hedge Fund and other open-source trading frameworks. Watch every agent work live, benchmark different LLMs on the same framework and backtest their decisions. Ships with 77 recorded runs and their full logs, so everything can be checked before spending a cent.
Research tool · paper accounts only · not investment advice
A rating is the last line of a long conversation between twelve agents. Glassbench keeps the whole conversation, so any rating can be checked against what produced it.
TradingAgents 0.5.1 and AI Hedge Fund 2.4.0 run as released. Glassbench observes each one through its own adapter with its own tests, so an engine update breaks in one known place and nowhere else.
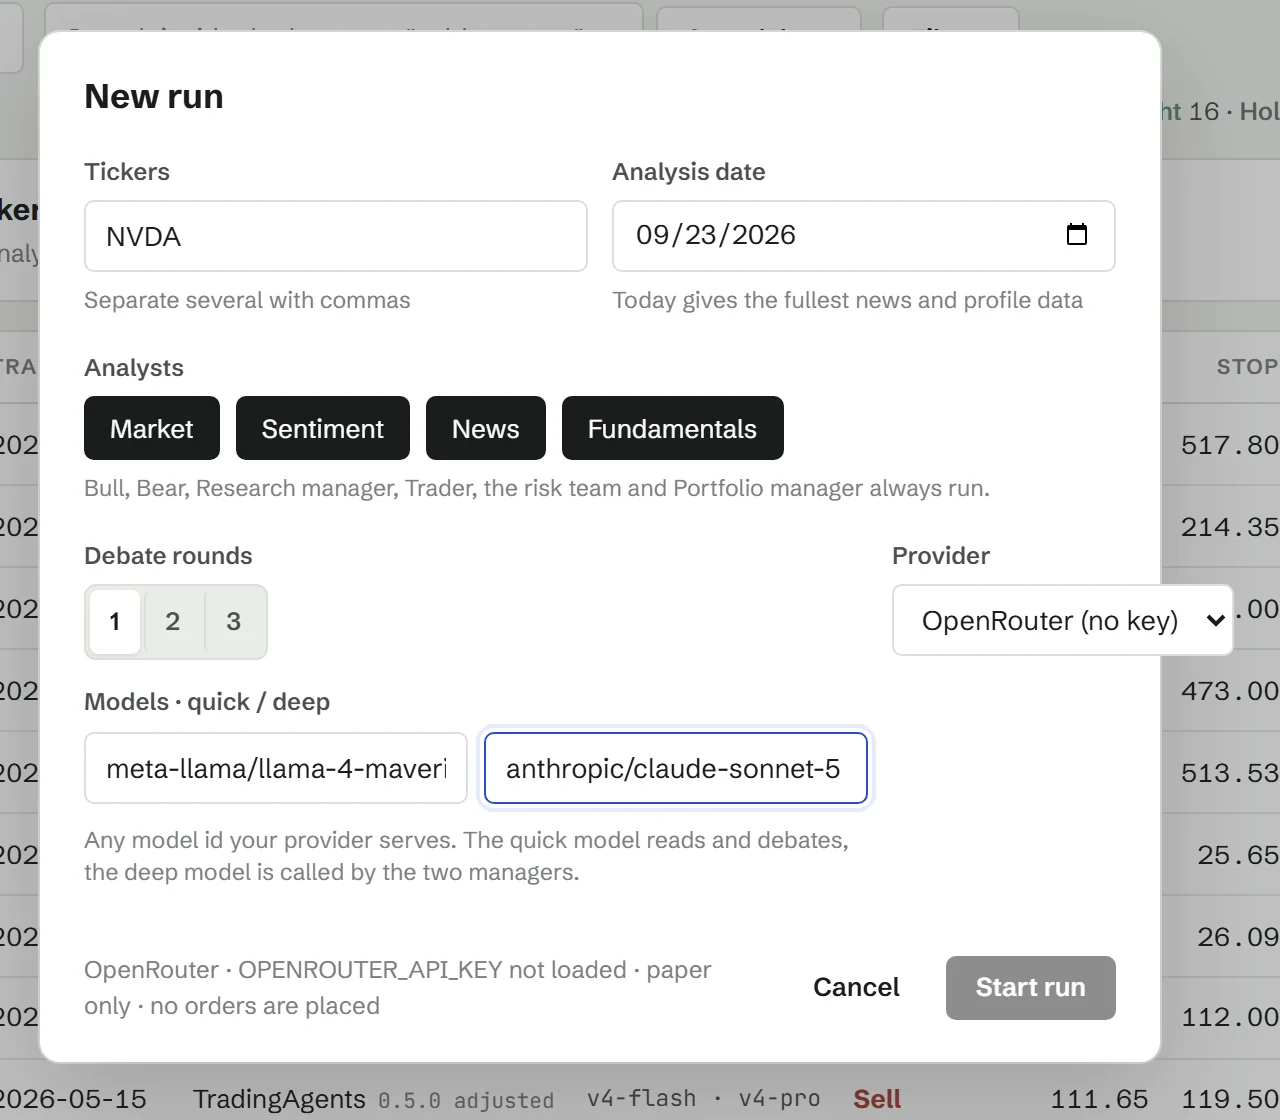
Any provider the engine supports and any model id you type. Cheap fast models read and debate; only the two managers call the expensive one, twice per run.
Every prompt, reasoning trace, tool call and result lands in SQLite as a numbered event. Searchable, exportable, and replayable step by step long after the run ended.
Most AI trading tools hand over a signal. Glassbench hands over the committee that produced it, with the receipts.
Twelve agents in five stages, each on its own card: what it is reading, what it is writing, what it concluded. Click one for every LLM call, every tool result and the reasoning as it streams, then replay the whole run later.
Every run lands in SQLite with its framework version, models, ticker, date, rating, levels, tokens and cost. Filter on any field, search the full text of every report and reasoning trace, and export any view to CSV.
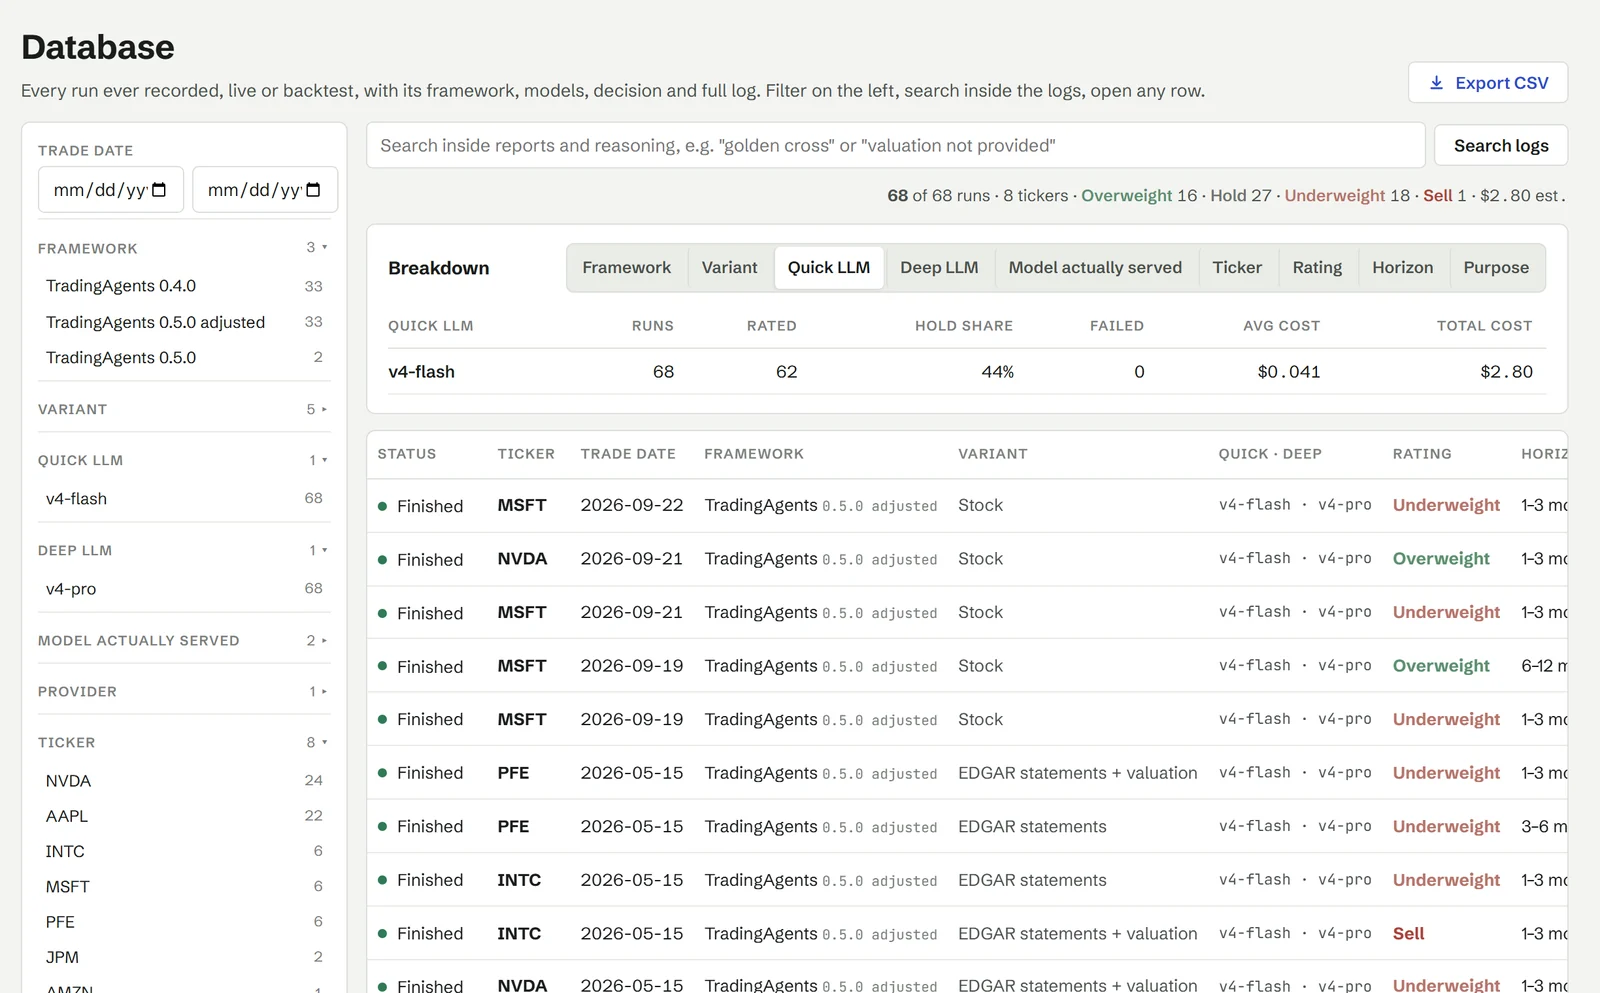
Keep the framework fixed and swap the models. Pick any of 13 providers, type any model id for the quick and deep roles, and compare the runs side by side with their cost. DeepSeek, the default, costs about six cents a run.
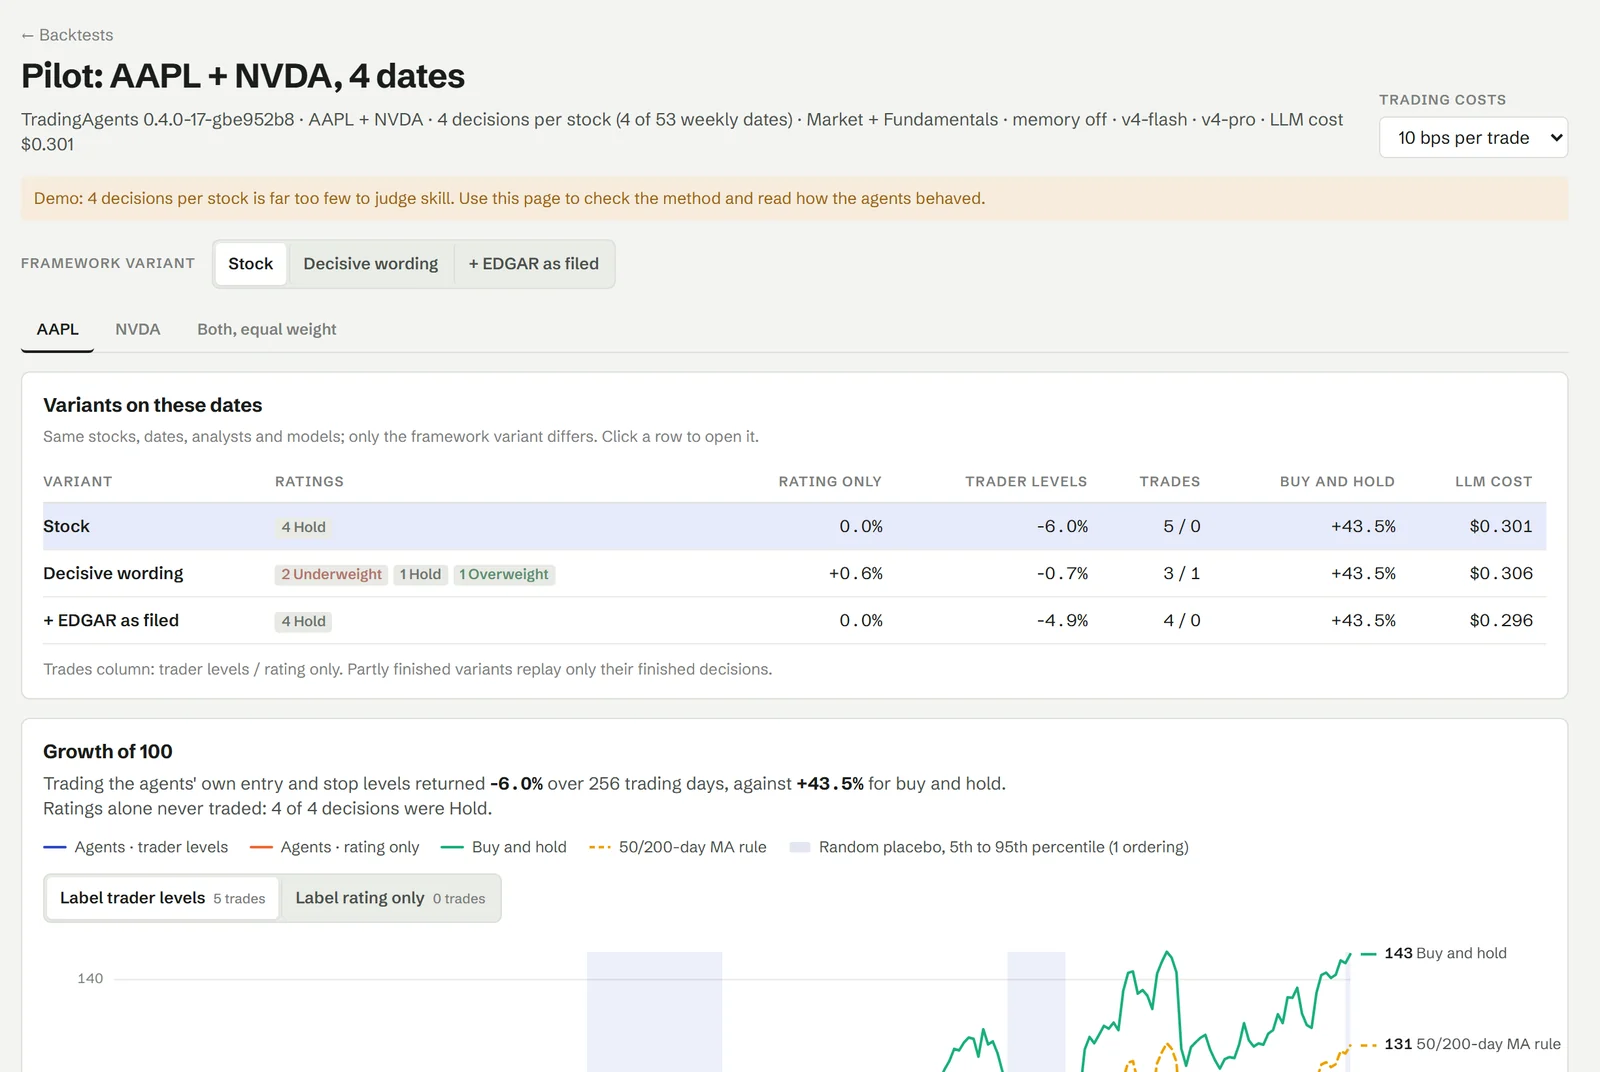
Weekly grids of past dates with a budget cap, replayed against buy and hold, a moving average rule and a shuffled rating placebo, with next open fills and trading costs. On the first pilot, buy and hold won on both stocks.
Entry, stop and target are what a broker needs. One script sends the committee's decision to an Interactive Brokers paper account as a bracket order, and the order stays linked to the run that argued for it.
Committee decision to filled bracket order, target and stop attached, on an Interactive Brokers paper account.
Same engine, same agents, same prompts. Glassbench changes what you can see, keep and compare.
| TradingAgents terminal | Glassbench | |
|---|---|---|
| Follow a run | A status table and a scrolling feed of messages | One card per agent with what it is doing and what it concluded, a stage strip and a timeline of every call |
| Open one agent | Scroll back through the terminal | Every LLM call with its tokens, every tool call with its full result, the reasoning stream, one click away |
| Replay | Not available | Any run, step by step, long after it finished |
| Compare runs | A report folder per run | Every run in one table, filtered on any field, exported to CSV |
| Search the logs | Grep the files | Full text search over every report and every reasoning trace |
| Cost | Token counts at the bottom of the screen | Tokens and dollar cost stored per run and per agent |
| Models | Any supported provider, picked at the prompt | Any provider and model id, recorded per run next to the model actually served |
| Backtest | A grid of runs scored on realised alpha | Weekly grids with a budget cap, replayed with fills and costs against buy and hold, a moving average rule and a placebo |
| Change what agents read | Edit the engine | Named variants applied per run, with the engine untouched |
| Send to a broker | Not available | One bracket order at an Interactive Brokers paper account, linked to its run |
Not investment advice. Ratings, price levels and reports below are language model output from a research tool, published so the method can be judged. None of it is a recommendation to buy, sell or hold any security.
Glassbench ships with the database of every run made while building it, complete logs included: every report, every tool output, every reasoning trace, and what each run cost. Open it in the app, query the SQLite file, or read any run on GitHub from the table below. No API key needed.
Trim MSFT toward 0.5 to 0.75x a standard allocation, a 25 to 50% reduction, not an exit. Use strength into the 498.98 to 505.06 supply zone as the preferred trim window.Open run 2e8c on GitHub →
Build MSFT toward an Overweight using a scaled entry, but start smaller than the original plan: take a quarter to a third of the intended overweight target near 493.78.Open run 2938 on GitHub →
| Date | Ticker | Rating | Entry | Stop | Target | Horizon | Models | Engine | Cost | Logs |
|---|
Every row links to its folder on GitHub: analyst reports, both debates, trader proposal, risk debate, final decision, every tool output and the final state. All of it also lives in data/desk.db, which opens in the app with no key at all.
Two results from the published database, with the method written down and the limits stated next to the numbers.
| Strategy | AAPL | NVDA | Equal weight |
|---|---|---|---|
| Agents, trader levels | -6.0% | -7.4% | -6.7% |
| Agents, rating only | 0.0% | 0.0% | 0.0% |
| Buy and hold | +43.5% | +29.6% | +36.6% |
| 50/200 day MA rule | +31.0% | +29.6% | +30.3% |
Each framework plugs in through its own adapter and keeps its own name and version on every run, so results from different frameworks never blur together.
A trading firm in twelve agents: four analysts pull data, a bull and a bear argue, a research manager writes a plan, a trader proposes levels, three risk debaters push back and a portfolio manager rates the stock on a five point scale.
A fund in agents: investor personas and an earnings drift model each signal the stock, their blended conviction passes risk limits and a simulated fill. Glassbench runs it untouched in its own environment, shows every analyst as a lane and maps the blend to the same five ratings, so both frameworks land in one table.
Python 3.11 or newer, Node 22 or newer, Git, and a key for one LLM provider. Reading the published runs needs no key at all.
Clone Glassbench, clone the engine next to it at its released tag, install both, add a key.
> git clone https://github.com/davidalmeida90/glassbench.git
> cd glassbench
> git clone --branch v0.5.1 --depth 1 https://github.com/TauricResearch/TradingAgents.git
> py -3.11 -m venv .venv
> .\.venv\Scripts\Activate.ps1
> pip install -r requirements.txt
> pip install -e .\TradingAgents
> copy .env.example .env     # paste your key
> .\glassbench.ps1
$ git clone https://github.com/davidalmeida90/glassbench.git
$ cd glassbench
$ git clone --branch v0.5.1 --depth 1 https://github.com/TauricResearch/TradingAgents.git
$ python3 -m venv .venv
$ source .venv/bin/activate
$ pip install -r requirements.txt
$ pip install -e ./TradingAgents
$ cp .env.example .env       # paste your key
$ ./glassbench.sh
Open http://127.0.0.1:8765 once the frontend finishes its first build.
# no browser: one run from the command line
$ cd backend
$ python -m deskapp run NVDA --analysts market,news,fundamentals
Open source under Apache 2.0. Clone it, run your own committee, or start with the logs database of the 77 that already ran.
Licensed portfolio manager and CFA charterholder, working on emerging markets private debt, derivatives and quantitative finance. Every model on davidariasfinance.com ships with its code and its write up, and Glassbench follows the same rule: the method, the runs and the results are all public.
One short email when something ships: a new framework adapter, a new batch of runs with their logs, or a backtest that says something. No spam.